Coder powers secure, scalable development across key industries — automotive, finance, government, and technology — enabling faster builds, tighter compliance, and seamless AI adoption in enterprise-grade cloud environments.
Administrators configure LLM providers from Admin settings > AI and
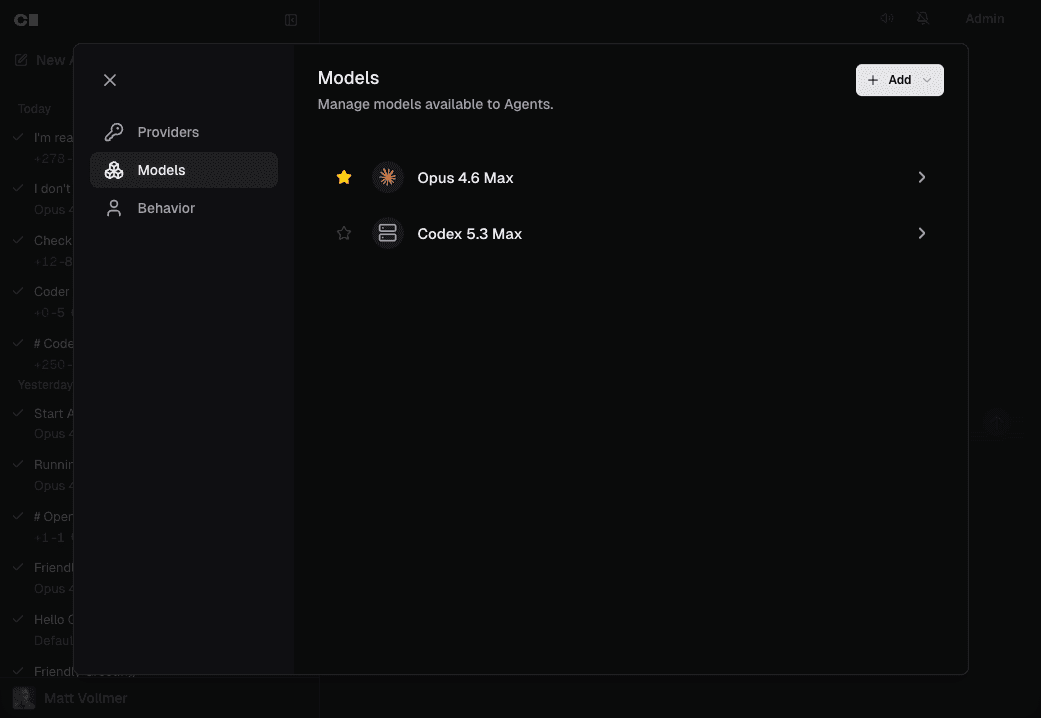
Coder Agents models from Admin settings > AI > Models. Providers,
models, and centrally managed credentials are deployment-wide settings managed
by platform teams. Developers select from the set of models that an administrator has
enabled.
Optionally, administrators can enable AI Gateway Bring Your Own Key (BYOK)
so developers can supply personal API keys for providers. See
User API keys below.
Providers
Each LLM provider has a type, credentials, and an endpoint/base URL for the
upstream provider or proxy.
Coder supports the following provider types:
Provider
Description
Anthropic
Claude models via Anthropic API
OpenAI
GPT and o-series models via OpenAI API
Google
Gemini models via Google AI API
Azure OpenAI
OpenAI models hosted on Azure
AWS Bedrock
Models via AWS Bedrock
OpenAI Compatible
Any endpoint implementing the OpenAI API
OpenRouter
Multi-model routing via OpenRouter
Vercel AI Gateway
Models via Vercel AI SDK
The OpenAI Compatible type is a catch-all for any service that exposes an
OpenAI-compatible chat completions endpoint. Use it to connect to self-hosted
models, internal gateways, or third-party proxies like LiteLLM.
Coder Agents route model requests through AI Gateway automatically by using
the provider configuration stored in Coder's database.
Some provider types work as AI Gateway proxy targets but cannot back Coder
Agents. GitHub Copilot, for example, authenticates with a per-request token
that only an official Copilot client can mint, so the server-side Agents
harness cannot use it. Configuring such a provider does not unlock Agents;
add one of the supported provider types above instead.
Add a provider
LLM providers are managed from the deployment AI settings, not from the Agents
settings page.
Navigate to Admin settings > AI.
Select Providers.
Click Add provider.
Select the provider type.
Enter a unique lowercase provider name, the credentials, and the upstream
provider or proxy
endpoint/base URL.
Click Save.
After saving a provider, add an Agents model for it from Admin settings >
AI > Models. For provider-specific setup, including AWS Bedrock, see
AI Gateway provider configuration.
Endpoint/base URL for OpenAI-compatible providers
Provider configuration stores an absolute HTTP(S) endpoint/base URL. Syntax
validation confirms that the value is a URL, but it does not prove the upstream
implements the APIs Coder sends.
For the default Agents path through AI Gateway, set the endpoint/base URL to
the upstream provider or proxy endpoint. Do not set it to Coder's public AI
Gateway route, such as https://<coder-host>/api/v2/ai-gateway/openai/v1.
OpenAI-shaped provider types require the upstream OpenAI-compatible prefix in
the endpoint/base URL because Coder appends request suffixes such as
/chat/completions, /responses, and /models. This applies to OpenAI,
Azure OpenAI, Google, OpenAI Compatible, OpenRouter, and
Vercel AI Gateway provider types.
Confirm the exact endpoint/base URL in your provider or proxy documentation.
Provider credentials and security
Provider API keys entered in the dashboard are stored encrypted in the Coder
database. They are never exposed to workspaces, developers, or the browser
after initial entry. The dashboard shows only whether a key is set, not the
key itself.
Because the agent loop runs in the control plane, workspaces never need direct
access to LLM providers. See
Architecture for details
on this security model.
Credential selection
Coder Agents use the AI providers configured by administrators. Provider API
keys entered by administrators are centralized credentials for the deployment.
BYOK for Coder Agents is controlled by the
global AI Gateway BYOK setting,
not by per-provider key policy flags. When BYOK is enabled, users can save a
personal API key for any enabled AI provider. When BYOK is disabled, saved user
keys are ignored and users cannot add or update personal keys.
For each provider request, Coder selects credentials in this order:
If BYOK is enabled and the user has saved a personal key for the selected
provider, Coder uses the user's key.
Otherwise, Coder uses centralized provider credentials when they are
configured.
If neither a usable user key nor centralized credentials are available, the
provider is unavailable for that user.
Models
Each model belongs to a provider and has its own configuration for context limits,
generation parameters, and provider-specific options.
Add a model
Navigate to Admin settings > AI > Models.
Click Add and select the provider for the new model.
Enter the Model Identifier, the exact model string your provider
expects (e.g., claude-opus-4-6, gpt-5.3-codex).
Set a Display Name so developers see a human-readable label in the model
selector.
Set the Context Limit, the maximum number of tokens in the model's
context window (e.g., 200000 for Claude Sonnet).
Configure any provider-specific options (see below).
Click Save.
The models list shows all configured models grouped by provider.
Adding a model requires a model identifier, display name, and context
limit. Provider-specific options appear dynamically based on the selected
provider.
Set a default model
Click the star icon next to a model in the models list to make it the
default. The default model is pre-selected when developers start a new chat.
Only one model can be the default at a time.
Models with a missing or disabled provider
The Models list reflects whether each model can actually be used:
When a model's connected provider has been deleted, the Provider column
shows Unset with an info tooltip that reads "The provider connected to
this model has been deleted."
When a model's provider is missing or disabled, the Status column
shows Disabled, regardless of the model's own enabled setting. Such a
model cannot serve chat requests.
To reconnect a model to a working provider, open the model from the list,
pick a new provider from the Provider dropdown, and click Save. The
Save button is enabled as soon as the selected provider differs from the
model's current provider, even if no other field is edited.
Model options
Every model has a set of general options and provider-specific options.
The admin UI generates these fields automatically from the provider's
configuration schema, so the available options always match the provider type.
General options
These options apply to all providers:
Option
Description
Model Identifier
The API model string sent to the provider (e.g., claude-opus-4-6).
Display Name
The label shown to developers in the model selector.
Context Limit
Maximum tokens in the context window. Used to determine when context compaction triggers.
Compression Threshold
Percentage (0-100) of context usage at which the agent compresses older messages into a summary.
Max Output Tokens
Maximum tokens generated per model response.
Temperature
Controls randomness. Lower values produce more deterministic output.
Top P
Nucleus sampling threshold.
Top K
Limits token selection to the top K candidates.
Presence Penalty
Penalizes tokens that have already appeared in the conversation.
Frequency Penalty
Penalizes tokens proportional to how often they have appeared.
Input Price
Optional USD price metadata for input tokens, recorded per 1M tokens.
Output Price
Optional USD price metadata for output tokens, recorded per 1M tokens.
Cache Read Price
Optional USD price metadata for cache read tokens, recorded per 1M tokens.
Cache Write Price
Optional USD price metadata for cache creation/write tokens, recorded per 1M tokens.
Provider-specific options
Each provider type exposes additional options relevant to its models. These
fields appear dynamically in the admin UI when you select a provider.
Sends the anthropic-beta: context-1m-2025-08-07 header to unlock the 1M token context window on supported Claude models. Pair it with a raised Context Limit, which still controls compaction. Long-context pricing may apply.
OpenAI
Option
Description
Reasoning Effort
How much effort the model spends reasoning (minimal, low, medium, high, xhigh).
Max Completion Tokens
Cap on completion tokens for reasoning models.
Parallel Tool Calls
Whether the model can call multiple tools at once.
Google
Option
Description
Thinking Budget
Maximum tokens for the model's internal reasoning.
Include Thoughts
Whether to include thinking traces in the response.
OpenRouter
Option
Description
Reasoning Enabled
Enable extended reasoning mode.
Reasoning Effort
Reasoning effort level (low, medium, high).
Vercel AI Gateway
Option
Description
Reasoning Enabled
Enable extended reasoning mode.
Reasoning Effort
Reasoning effort level.
Note
Azure OpenAI uses the same options as OpenAI. AWS Bedrock uses the same
model configuration options as Anthropic (thinking budget, reasoning
effort).
How developers select models
Developers see a model selector dropdown when starting or continuing a chat on
the Agents page. The selector shows only models from providers that have valid
credentials configured. Models are grouped by provider if multiple providers
are active.
The model selector uses the following precedence to pre-select a model:
Last used model, stored in the browser's local storage.
Admin-designated default, the model marked with the star icon.
First available model, if no default is set and no history exists.
Developers cannot add their own providers or models. If no models are
configured, the chat interface displays a message directing developers to
contact an administrator.
Model overrides
Beyond the chat-level model picker, Coder Agents supports two override
layers:
Subagent overrides (admin, deployment-wide): Pin specific subagent
contexts to a particular model. Configure them at Agents >
Settings > Manage Agents > Agents.
Personal overrides (per user, opt-in by admin): Let users override
the model for their own root chats and delegated subagents. Admins
enable the toggle on the same admin page; once on, each user sees an
Agents tab in their personal Agents > Settings.
The configurable contexts:
Context
Layer
Applies to
General
Admin + user
Write-capable subagents (spawn_agent with type=general or computer_use).
Explore
Admin + user
Read-only subagents (spawn_agent with type=explore).
Title generation
Admin only
Automatic title generation for new chats.
Root
User only
The user's own root chats.
Resolution order, evaluated per chat or subagent:
Explicit model_config_id on the spawn_agent tool call (general and
explore subagents only).
Personal override (when the admin gate is on and a model is set).
Admin subagent override.
The chat's selected model (or the deployment default for new chats).
If a referenced model is later disabled or deleted, that layer is skipped
and resolution falls through to the next. Explicit spawn_agent selection
is different: an unusable model_config_id fails the tool call instead of
falling through. Agents discover selectable models (and their reasoning
effort ranges) with the list_subagent_models tool, which only returns
enabled models usable with the chat owner's credentials. Computer-use
subagents always run on the administrator-configured computer-use model and
reject explicit model selection.
Note
Both override layers are experimental and may change between releases.
The same values are available through the experimental chat
configuration API under /api/experimental/chats/config/.
User API keys (BYOK)
When AI Gateway BYOK is
enabled, developers can supply personal API keys for any enabled AI provider
from the Agents settings page.
Managing personal API keys
Navigate to the Agents page in the Coder dashboard.
Open Settings and select the API Keys tab.
Each enabled provider is listed with a status indicator:
Key saved, your personal key is active and will be used for requests to
that provider.
Using shared key, no personal key is set and Coder is using
deployment-managed credentials for that provider.
No key, no personal key or deployment-managed credential is available.
Add a personal key before you use models from this provider.
Enter your API key and click Save.
Personal API keys are encrypted at rest using the same database encryption
used for deployment-managed provider secrets. The dashboard never displays a
saved key, only whether one is set.
Removing a personal key
Click Remove on the provider card in the API Keys settings tab. Subsequent
requests use deployment-managed credentials when they are configured for that
provider. If no deployment-managed credential is available, add a new personal
key before you use models from that provider.
Using an LLM proxy
Organizations that route LLM traffic through a centralized proxy, such as
LiteLLM or an internal gateway, can point a provider's Endpoint or Base
URL at that upstream proxy endpoint. Enter the API key your proxy expects.
Use the OpenAI Compatible provider type if your proxy serves multiple model
families through a single OpenAI-compatible endpoint. Include the proxy
provider's documented OpenAI-compatible path prefix, such as /v1, when
required.
This lets you keep existing proxy-level features like per-user budgets, rate
limiting, and audit logging while using Coder Agents as the developer interface.